
Why Spector Memory Uses 64-Byte Fixed Binary Cognitive Headers Instead of NoSQL JSON, SQL Row, or Columnar Storage
Executive Summary & Architectural Context
Building autonomous AI agent memory engines demands a fundamental rethinking of storage layout dynamics. An AI agent memory record is not merely an isolated embedding vector; it is a multi-signal cognitive entry containing temporal markers, emotional valence/arousal, prediction-error importance scores, Bloom filter tag masks, and reinforcement counters alongside high-dimensional float32 or quantized vectors.
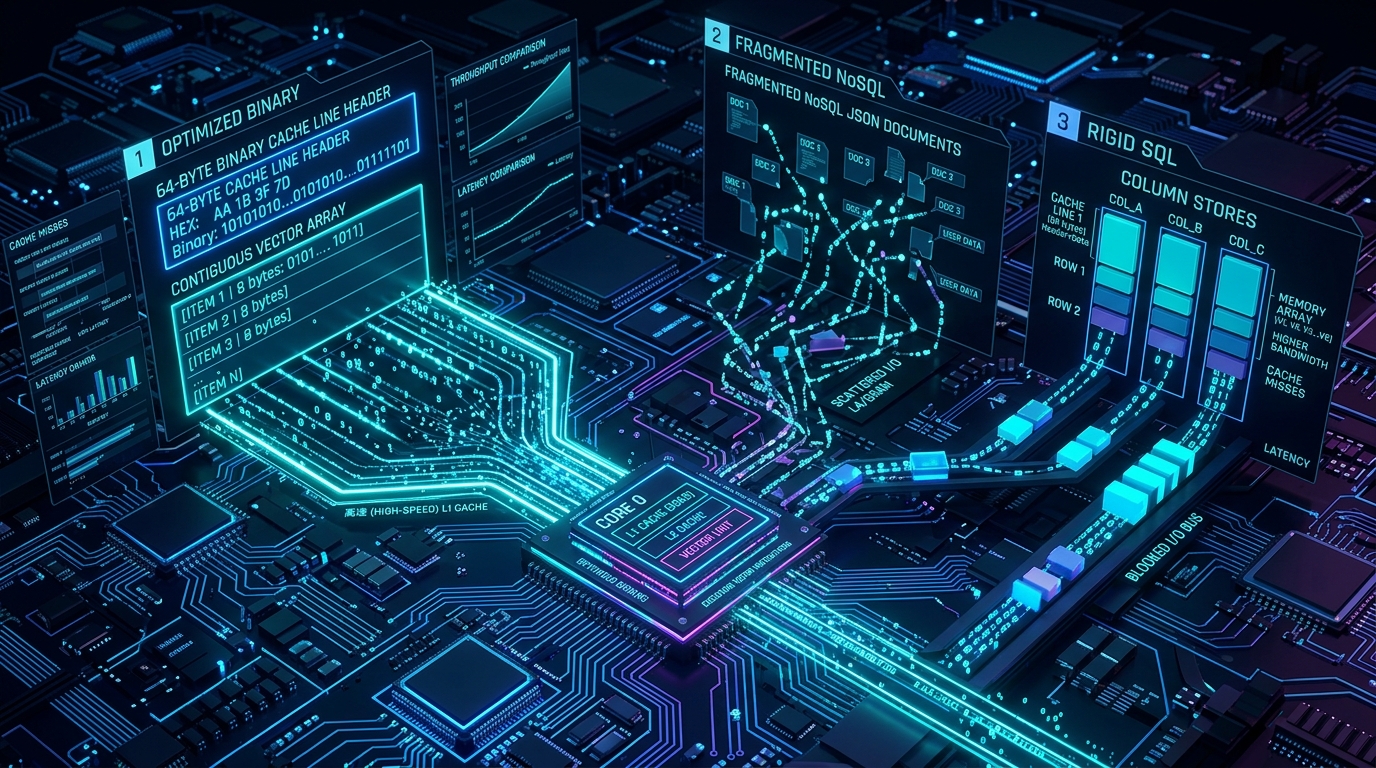
When designing Spector Memory, we evaluated four distinct storage paradigms for persisting and retrieving cognitive records:
- NoSQL Document Stores (JSON / BSON): Dynamic, schema-flexible key-value document trees (e.g., MongoDB, Couchbase, Elasticsearch).
- SQL Row Stores (PostgreSQL / MySQL): Traditional row-oriented relational databases with B-tree indexing and MVCC concurrency.
- SQL Columnar Stores (Parquet / DuckDB / ClickHouse): Column-oriented storage optimized for analytical aggregates (
SUM,AVG) across isolated fields. - Fixed Binary Cognitive Headers (Off-Heap L1 Cache-Line Aligned): Hardware-tailored, zero-parse 64-byte binary headers paired directly with contiguous vector payloads in native memory via Java 25 Foreign Function & Memory (FFM).
Our architectural analysis showed that NoSQL JSON documents incur a ~3.75x storage expansion and significant GC pressure. Traditional SQL row stores like PostgreSQL introduce tuple header overhead, TOAST fragmentation for large vectors, and MVCC versioning costs that bloat storage and slow sequential scans. SQL columnar formats suffer from CPU L1 cache misses during multi-signal fused scoring because gathering fields across six isolated column buffers requires six random memory jumps per candidate record.
Note: Spector's cognitive header is an in-process off-heap memory engine — it operates at a fundamentally different layer than external database servers like MongoDB, PostgreSQL, or DuckDB, which include networking, query parsing, and transaction management overhead. This article focuses on the storage layout and CPU cache efficiency tradeoffs, not a benchmark of complete database systems.
This article details the engineering rationale, memory layout mechanics, and performance advantages of Spector's 64-byte cache-line aligned binary header.
1. The Architectural Bottleneck of NoSQL JSON Document Stores
NoSQL document databases gained massive popularity for web applications due to schema flexibility. However, for real-time vector search and cognitive memory recall, JSON/BSON structures introduce fundamental inefficiencies at the storage and CPU levels.
flowchart TD
subgraph J["NoSQL JSON Document - On Heap"]
direction TB
K1["id: mem_994821"] --- K2["timestamp_ms: 17549..."]
K2 --- K3["importance: 0.854210"]
K3 --- K4["valence: -12"]
K4 --- K5["tags: array ptr to Heap"]
K5 --- K6["embedding: 768 boxed Doubles"]
end
K1 -.- P1["String key duplication\nper document"]
K3 -.- P2["ASCII float: 15 bytes\nvs 4 bytes binary"]
K6 -.- P3["Boxed Double 768\n~12 KB + GC pressure"]
The Three Friction Points of NoSQL Vector Engines
1. ASCII & BSON Serialization Tax
In raw binary float32 representation, a single vector dimension requires exactly 4 bytes. In standard JSON, a float like -0.04512398471 is stored as an ASCII string consuming 15 bytes — a ~3.75x expansion (275% overhead). A 768-dimensional float32 vector (3,072 bytes binary) expands to over 12 KB of JSON text. Even BSON incurs field key overhead ("embedding":) repeated redundantly across millions of documents.
2. Heap Allocations & Garbage Collection Storms
Deserializing a JSON document into Java/Node objects during recall queries instantiates thousands of transient objects per query (JSONObject, HashMap$Node, Double[], String). Under high-throughput recall (10,000 concurrent Virtual Threads), GC memory throughput saturates, causing major stop-the-world latency spikes.
3. Breakdown of Hardware SIMD Acceleration
Modern hardware relies on CPU SIMD intrinsics (AVX-512, ARM Neon) to compute dot products or L2 distances across 16 float values simultaneously in a single CPU instruction. JSON float arrays reside as pointers to boxed object wrappers scattered across heap memory. Fetching numbers requires pointer dereferencing, completely blocking C2 JIT auto-vectorization.
2. The Architectural Bottleneck of SQL Row Stores (PostgreSQL)
Traditional row-oriented relational databases like PostgreSQL store each row contiguously on disk — which sounds ideal for record-by-record access. However, for high-density AI vector workloads, PostgreSQL introduces several structural inefficiencies.
PostgreSQL Tuple Overhead
Every PostgreSQL heap tuple carries a 23-byte fixed header (HeapTupleHeaderData) containing transaction visibility information (xmin, xmax, cid), tuple flags, and a null bitmap pointer. For a cognitive record that is only 64 bytes of metadata + vector payload, a 23-byte per-row system header represents significant overhead.
flowchart LR
subgraph PG["PostgreSQL Heap Page - 8 KB"]
direction TB
PH["Page Header\n24 bytes"] --> LP["Line Pointers\n4 bytes each"]
LP --> T1["Tuple 1"]
LP --> T2["Tuple 2"]
LP --> T3["Tuple 3"]
end
subgraph TUP["Single Tuple Layout"]
direction LR
TH["Tuple Header\n23 bytes\nxmin, xmax, flags"] --> ND["Null Bitmap\nvariable"] --> TD["User Data\nmetadata + vector"]
end
The Four Friction Points of SQL Row Stores
1. TOAST Fragmentation for Vectors
PostgreSQL's TOAST mechanism automatically moves large column values (> ~2 KB) to a separate TOAST table. A 768-dimensional float32 vector occupies 3,072 bytes — exceeding the TOAST threshold. This means the vector payload is stored out-of-line, requiring a second I/O hop to fetch it during scoring. Even with pgvector, the vector column is subject to TOAST rules, fragmenting what should be a contiguous record across separate heap pages.
2. MVCC Versioning Bloat
PostgreSQL's MVCC model creates a new physical copy of the entire tuple for every UPDATE. Spector's recall pipeline frequently updates agent_recall_count, spector_recall_count, storage_strength, and last_auto_ltp on recalled memories. In PostgreSQL, each of these lightweight 4-byte or 8-byte field updates would generate a full tuple copy (header + all columns), causing massive write amplification and table bloat requiring periodic VACUUM.
3. Buffer Pool Indirection
PostgreSQL accesses data through a shared buffer pool with page-level locking. Every row read requires: pin the buffer → acquire shared lock → copy data to local memory → release lock. For a brute-force scan over millions of cognitive records, this per-page locking protocol introduces contention that Spector's lock-free off-heap MemorySegment reads avoid entirely.
4. No In-Place Atomic Field Updates
Spector uses VarHandle.getAndAdd() to atomically increment recall counters and VarHandle.getAndBitwiseOr() to merge synaptic tags — all in-place, without copying the record. PostgreSQL has no equivalent: updating a single integer field requires creating a new tuple version, updating indexes, and eventually vacuuming the dead tuple.
3. The Architectural Bottleneck of SQL Columnar Storage
Columnar databases (e.g., Apache Parquet, DuckDB, ClickHouse) store data column-by-column on disk and in memory. This layout is unmatched for OLAP queries such as SELECT AVG(importance) FROM memories.
However, AI agent recall is fundamentally a fused multi-signal candidate search:
flowchart TD
subgraph S1["SQL Columnar Storage - Scattered Memory"]
C1[Column 1: Timestamp]
C2[Column 2: Flags]
C3[Column 3: Importance]
C4[Column 4: Valence]
C5[Column 5: Bloom Tags]
C6[Column 6: Vector Array]
end
Query[Recall Query] -->|Cache Miss| C1
Query -->|Cache Miss| C2
Query -->|Cache Miss| C3
Query -->|Cache Miss| C4
Query -->|Cache Miss| C5
Query -->|Cache Miss| C6
C1 & C2 & C3 & C4 & C5 & C6 -->|Stitched on Heap| SC["Scored Candidate"]
Why Columnar Storage Fails in Agentic Memory
Cache Line Trashing during Candidate Scoring: To score a candidate memory record, Spector computes a fused score incorporating temporal decay (
timestamp_ms), emotional weight (valence,arousal), prediction error (importance), and contextual Bloom filters (synaptic_tags). In a columnar layout, accessing these six attributes for candidate record #4,821 requires reading from six completely separate memory regions. This causes six distinct CPU cache misses per record evaluated, destroying hardware L1/L2 prefetcher efficiency.Random Assembly Overhead: Gathering non-contiguous column fields into a candidate tuple requires array index math and heap assembly for every item during scan iterations, introducing unnecessary memory barrier synchronization.
4. The Spector Solution: 64-Byte Cache-Line Aligned Binary Cognitive Header
To eliminate serialization taxes, GC allocations, TOAST fragmentation, MVCC bloat, and columnar cache misses, Spector Memory implements a 64-byte cache-line aligned binary cognitive header paired with a contiguous off-heap vector payload.
The 64-Byte Binary Layout
Modern CPU architectures (x86-64, ARM64) fetch memory from main RAM into CPU L1/L2 caches in 64-byte cache lines. By packing 100% of core cognitive metadata into exactly 64 bytes, a single memory fetch loads all decision fields into CPU registers in one L1 cache line access.
The layout is defined across three classes: SynapticHeaderConstants (offsets and flag bitmasks), HeaderLayout (a sealed interface defining versioned read/write contracts), and HeaderLayout64 (the sole implementation, performing direct MemorySegment reads at each offset).
Offset  Size  Field               Access Phase  Function
──────  ────  ──────────────────  ────────────  ──────────────────────────────
 0      1B    header_version      One-time      Format version detection
 1      1B    flags               Phase 1       Tombstone, type, modality, pinned, resolved
 2      1B    valence             Phase 3       Signed emotion (-128 to +127)
 3      1B    arousal             Phase 4.5     Emotional intensity (0 to 255)
 4      4B    importance          Phase 4       Base prediction-error float
 8      8B    timestamp_ms        Phase 1b      Epoch timestamp for decay curve
16      4B    agent_recall_count  Phase 4       LTP reinforcement counter
20      4B    exact_norm          Heap insert   L2 norm for vector distance
24      8B    synaptic_tags       Phase 2       64-bit Bloom filter tag mask
──────  32B: End of Core Fields ─────────────────────────────────────────────
32      2B    centroid_id         Heap insert   IVF partition routing ID
34      1B    consolidation_flg   Phase 5       Contradiction & reflection flags
35      1B    _pad0               —             Alignment padding
36      4B    storage_strength    Phase 6       Two-Factor storage strength float
40      4B    spector_recall_cnt  Auto-LTP      Internal retrieval counter
44      4B    _reserved_f1        —             Reserved future float field
48      8B    last_auto_ltp       Auto-LTP      Last LTP timestamp
56      4B    _reserved_l1a       Future        Future 128-bit Bloom tag upper half
60      1B    last_recall_profile Auto-LTP      CognitiveProfile ordinal from last recall
61      3B    _reserved_l1b       Future        Remaining reserved bytes
──────  64B: Full Cache Line Boundary ───────────────────────────────────────
Biological Analog: The Synaptic Tag
In neuroscience (Frey & Morris, 1997), active synapses are marked with chemical "tags" during learning. Spector's 64-byte header serves as a digital synaptic tag: a lightweight, cache-resident marker that allows microsecond-latency routing, filtering, and scoring without touching the heavy off-heap vector payload.
5. Architecture: Sealed Header Hierarchy & Off-Heap FFM Execution
Spector leverages Java 25 FFM (java.lang.foreign) to slice, read, and atomically update 64-byte headers directly in unmanaged off-heap memory via MemorySegment. The architecture separates concerns into three layers:
flowchart TB
subgraph HL["Header Architecture - Sealed Hierarchy"]
direction TB
SC["SynapticHeaderConstants\nOffsets, Flags, Bitmasks"]
HI["HeaderLayout\nSealed Interface"]
H64["HeaderLayout64\n64B Implementation"]
SC --> HI
HI --> H64
end
subgraph CRL["CognitiveRecordLayout"]
direction TB
CH["CognitiveHeader\nImmutable Java Record"]
ST["stride = 64B header\n+ quantized vector bytes"]
end
subgraph MEM["Off-Heap MemorySegment"]
direction LR
MS["MemorySegment.get/set\nZero-copy, Zero-GC"]
VH["VarHandle Atomics\nCAS, getAndAdd, getAndBitwiseOr"]
end
H64 -->|"reads/writes via"| MEM
CRL -->|"delegates to"| HI
CH -->|"returned by"| H64
Key design decisions:
SynapticHeaderConstantsdefines all byte offsets,ValueLayouttype descriptors, flag bitmasks, and pure-function flag checks (e.g.,isTombstoned(byte flags)takes a pre-readbyte, not aMemorySegment).HeaderLayoutis a sealed interface defining the versioned read/write contract. This allows future header layouts (e.g., 128-byte) without touching the record layout or scoring code.HeaderLayout64is the sole implementation, performing directMemorySegment.get()/.set()reads at each constant offset. Atomic mutations (recall count increments, synaptic tag merges) useVarHandle.getAndAdd()andVarHandle.getAndBitwiseOr()for lock-free thread safety.CognitiveRecordLayoutwraps the header layout and computes the full record stride. The innerCognitiveHeaderis an immutable Java record — a candidate for JEP 401 (Value Classes) scalarization in future JDK releases.
Zero-Allocation Stride Layout
Each cognitive memory record is laid out contiguously in memory:
$$\text{Stride} = \text{HeaderBytes } (64\text{B}) + \text{QuantizedVectorBytes}$$
For a 768-dimensional quantized vector (768 bytes), the total record stride is exactly $64 + 768 = 832$ bytes.
flowchart LR
subgraph S2["Contiguous Off-Heap Memory Segment"]
direction LR
H1["64B Header\nCache Line 1"] --> V1["768B Vector\nSIMD Buffer"]
V1 --> H2["64B Header\nCache Line 2"] --> V2["768B Vector\nSIMD Buffer"]
V2 --> H3["64B Header\nCache Line 3"] --> V3["..."]
end
6. Four-Way Architectural Comparison
The following table compares the four storage paradigms on fundamental architectural properties. These are theoretical characteristics derived from how each format handles serialization, memory layout, and CPU access patterns — not empirical benchmark results from a specific test run.
Storage Layout Comparison (768-dim float32 vector)
| Property | NoSQL JSON / BSON | SQL Row Store (PostgreSQL) | SQL Columnar (DuckDB) | Spector 64B Binary |
|---|---|---|---|---|
| Bytes per float dimension | ~15B (ASCII) / 8B (BSON) | 4B (native float32) | 4B (native float32) | 4B (or 1B quantized) |
| 768-dim vector payload | ~12 KB (JSON) / 6 KB (BSON) | 3,072B (but TOASTed out-of-line) | 3,072B | 768B (SQ8) – 3,072B (f32) |
| Per-record system overhead | ~200–500B (key strings, delimiters) | 23B tuple header + null bitmap + alignment | ~0B (schema-level) | 0B (header IS the data) |
| Per-record metadata overhead | Embedded in document | Column values stored inline or TOASTed | Column values in separate buffers | 64B fixed header |
| CPU cache behavior (scoring) | Parse-then-access; heap-scattered | Row-contiguous but TOAST hops for vectors | 6+ cache misses per candidate | 1 cache line for all metadata |
| GC / memory allocation | High (object tree deserialization) | Medium (buffer pool copies to heap) | Medium (column buffer copies) | Zero (off-heap MemorySegment) |
| SIMD compatibility | None (pointer indirection) | None (tuple format not SIMD-friendly) | Partial (within single column) | Full (contiguous vector bytes) |
| Atomic field updates | Document-level lock or re-write | Full tuple copy (MVCC new version) | Append-only / WAL | In-place VarHandle CAS |
| Update write amplification | Full document re-write | Full row copy + dead tuple + VACUUM | Append new row version | 4–8 bytes (single field) |
| Schema evolution | Flexible (dynamic keys) | ALTER TABLE + rewrite | ALTER TABLE / migration | Version byte + sealed HeaderLayout |
| Concurrency model | Document-level locks | MVCC with shared buffer pool locks | Read-optimized, limited concurrency | Lock-free VarHandle on off-heap |
Why the Layout Matters: Four-Way Access Pattern Comparison
flowchart LR
subgraph NQ["NoSQL: 1 Record"]
direction TB
NP["Parse JSON/BSON\nCPU + heap alloc"] --> NF["Chase heap pointers\nto each field"]
NF --> NV["Unbox Double 768\nfor vector math"]
end
subgraph PG["PostgreSQL: 1 Record"]
direction TB
PB["Pin buffer page\nacquire shared lock"] --> PR["Read tuple header\n23B system overhead"]
PR --> PT["TOAST fetch\nvector out-of-line"]
end
subgraph SQ["Columnar: 1 Record"]
direction TB
S1["Read timestamp\nColumn A, Cache Miss"] --> S2["Read flags\nColumn B, Cache Miss"]
S2 --> S3["Read importance\nColumn C, Cache Miss"]
S3 --> S4["Read valence\nColumn D, Cache Miss"]
end
subgraph SP["Spector: 1 Record"]
direction TB
B1["Load 64B header\n1 L1 cache line"] --> B2["All 14 fields\nin registers"]
B2 --> B3["SIMD scan\ncontiguous vector"]
end
- NoSQL: Every field access requires navigating a parsed object tree. Vector math requires unboxing 768
Doublewrappers — creating ~6 KB of transient garbage per record. - PostgreSQL: Row data is contiguous within a page, but the 23-byte tuple header adds overhead, TOAST fragments the vector out-of-line, and the buffer pool pin/lock protocol adds latency under concurrent load. Updating a single recall counter creates a full dead tuple requiring VACUUM.
- SQL Columnar: Scoring across six fields means six cache misses. The CPU prefetcher cannot predict the next column location, stalling the pipeline.
- Spector Binary: One 64-byte cache line prefetch delivers all 14 header fields. The vector payload begins at a known fixed stride offset, enabling the CPU prefetcher to stream contiguous bytes into SIMD registers. Field updates are in-place atomic operations with zero write amplification.
7. Key Takeaways & Enterprise Best Practices
Cache Line Alignment is Mandatory for AI Search: Padding metadata headers to match CPU 64-byte cache line boundaries eliminates L1/L2 cache misses, allowing multi-signal scoring routines to run at near-register speeds.
Ditch Text Formats for High-Density Vectors: JSON/BSON document representations introduce a ~3.75x storage expansion and destroy CPU SIMD auto-vectorization through pointer indirection.
Traditional SQL Row Stores Pay Hidden Taxes: PostgreSQL's MVCC tuple versioning, TOAST fragmentation, and buffer pool locking introduce write amplification and access latency that purpose-built off-heap layouts avoid entirely.
Avoid Columnar Scattering in Fused Row Scoring: While columnar layouts excel at single-column aggregations, candidate scoring across multiple cognitive attributes requires row-contiguous access to keep prefetchers saturated.
Off-Heap FFM Delivers Zero-GC Predictability: Decoupling AI memory structures from the JVM heap via Java 25 Foreign Function & Memory eliminates GC pauses and delivers predictable tail latencies at scale.
Sealed Interface Hierarchies Enable Layout Evolution: The
HeaderLayoutsealed interface allows introducing new header formats (e.g., 128-byte for expanded Bloom filters) without touching scoring code or record layouts.
Experience Spector Memory
Explore the open-source Spector codebase and see how our 64-byte fixed binary header powers real-time cognitive recall across multi-agent AI platforms:
- GitHub Repository: spectrayan/spector
- Header Constants:
SynapticHeaderConstants.java - Sealed Header Interface:
HeaderLayout.java - 64B Implementation:
HeaderLayout64.java - Record Layout:
CognitiveRecordLayout.java