
Zero-Downtime Cognitive Migration: Architecting Chunk-Oriented Memory Import & Export via Spring Batch
1. The Challenge of Migrating Statefulness in AI Memory
Traditional relational databases and document stores rely on familiar dump and restore patterns (pg_dump, mongodump). However, migrating autonomous AI agent memory presents unique architectural challenges. AI memory is not merely a collection of isolated text rows; it is an interdependent multi-tiered stateful engine comprising:
- Semantic Memory Nodes: Text records, metadata tags, key-values, and salience scores.
- Dense Vector Embeddings: Raw 768-dimensional
float32arrays powering ANN vector search. - Cognitive Hypergraphs: Associative links, graph hyperedges, and dynamic Hebbian weights.
- Biological Subsystems: Active state parameters from Hippocampal consolidation, Amygdala emotional valence, and Insular identity anchors.
- Security Tiers: Per-namespace encryption key headers and metadata.
If a migration tool only captures raw text or vector tables while ignoring hyperedges or Hebbian synapse weights, the agent suffers cognitive amnesia post-migration.
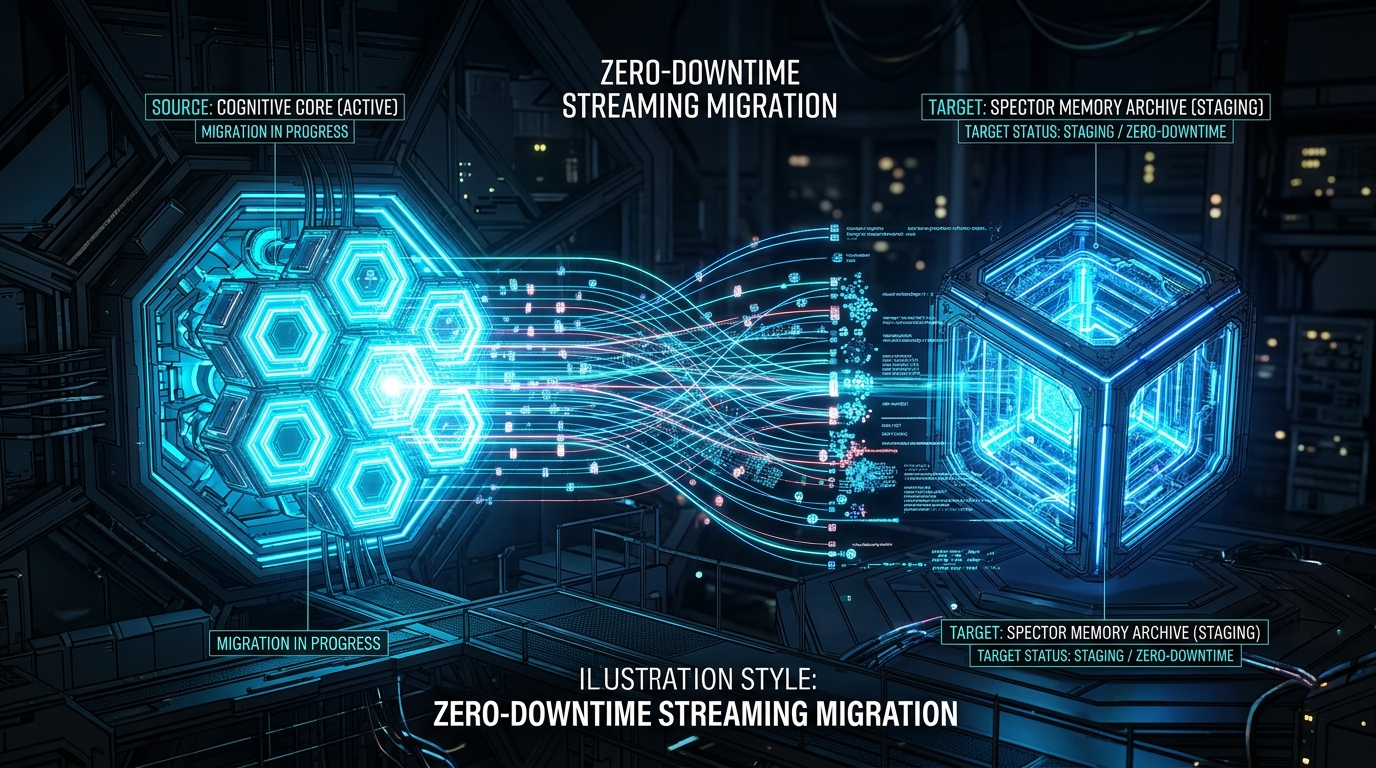
To overcome this, Spector Memory introduced synapse/spector-batch—a robust, chunk-oriented migration pipeline built on Spring Batch 6.x that packages complete cognitive state into portable Spector Memory Bundles (.smb).
graph TD
SubA["Memory Nodes & Tags"] --> Codec["SpectorBundleCodec"]
SubB["Dense Float32 Vectors"] --> Codec
SubC["Cognitive Hypergraphs"] --> Codec
SubD["Hebbian Synapse Weights"] --> Codec
SubE["Biological Subsystems"] --> Codec
SubF["Encryption Headers"] --> Codec
Codec --> SMB[".smb Archive (tar.zst)"]
2. Spring Batch 6.x Pipeline Topology
The migration pipeline in synapse/spector-batch is structured as an ordered, transactional Spring Batch Job consisting of eight dedicated step tasklets with pre-packaging count and integrity verification:
sequenceDiagram
autonumber
participant Job as ExportJob (Spring Batch)
participant M as exportManifestStep
participant N as exportMemoryNodesStep
participant V as exportVectorsStep
participant G as exportGraphStep
participant S as exportSubsystemsStep
participant K as exportKeysStep
participant Val as validateExportStep
participant P as packageBundleStep
Job->>M: 1. Generate manifest.json (schema & version)
Job->>N: 2. Export nodes, text & key-values
Job->>V: 3. Export contiguous vector float arrays
Job->>G: 4. Export hypergraph & Hebbian weights
Job->>S: 5. Export Hippocampus, Amygdala & Insula state
Job->>K: 6. Export encryption headers
Job->>Val: 7. Validate entity counts & checksums
Job->>P: 8. Compress verified staging into .smb archive
3. The Spector Memory Bundle (.smb) Specification
The Spector Memory Bundle (.smb) is a compressed tarball (tar.zst or .zip) formatted for high-density streaming I/O. Its internal directory structure guarantees isolated component validation:
bundle.smb
├── manifest.json
├── nodes/
│   └── memory_nodes.jsonl
├── vectors/
│   └── embeddings.bin
├── graph/
│   ├── hyperedges.jsonl
│   └── hebbian_weights.bin
├── subsystems/
│   ├── hippocampus.json
│   ├── amygdala.json
│   └── insula.json
└── security/
    └── encryption_meta.json
Manifest Schema Standard (manifest.json)
{
  "schemaVersion": "2.0.0",
  "namespace": "production-agent-v1",
  "exportTimestamp": "2026-08-13T10:00:00Z",
  "components": [
    "nodes",
    "vectors",
    "graph",
    "subsystems",
    "security"
  ]
}
4. Dual-Mode Operational Mechanics: REST & CLI
Migration operations are accessible through two complementary interaction surfaces:
Asynchronous REST Endpoint Architecture
The runtime engine exposes non-blocking HTTP endpoints (/api/v1/migration/export, /import, /jobs/{id}) for background job orchestration, non-blocking execution, and real-time status tracking across multi-node agent clusters.
Picocli CLI Operations (spectorctl memory export)
The CLI provides dual execution modes:
- Remote REST Proxy Mode (Default): Dispatches export/import commands over REST to a running server instance with sub-100ms startup latency.
- Embedded Offline Mode (
--offline): Direct Spring Batch invocation for air-gapped or standalone server maintenance when the HTTP daemon is offline.
# Export memory state remotely over REST
spectorctl memory export --namespace prod-agent --output /tmp/prod.smb

# Import memory state offline directly via embedded Spring Batch
spectorctl memory import --input /tmp/prod.smb --target-namespace staging-agent --offline
5. Key Takeaways & Enterprise Best Practices
- Never Trade Cognitive State for Storage Simplicity: True agentic memory requires capturing hyperedges and Hebbian synaptic weights alongside vector embeddings.
- Leverage Chunked Streaming: Spring Batch's tasklet and item reader model keeps memory allocation bounded (
<128 MB) regardless of dataset size. - Decouple CLI from Heavy Frameworks: Using a lightweight HTTP proxy pattern in
spectorctldelivers instantaneous CLI feedback (<100ms) while retaining offline batch fallback capabilities.
Experience Spector Memory
- GitHub Repository: spectrayan/spector
- Documentation & ADRs: ADR-0006 Architecture Spec