
The Episodic Log: How Spector Reinterprets 64-Byte Synaptic Headers for Sub-Microsecond Conversation Storage
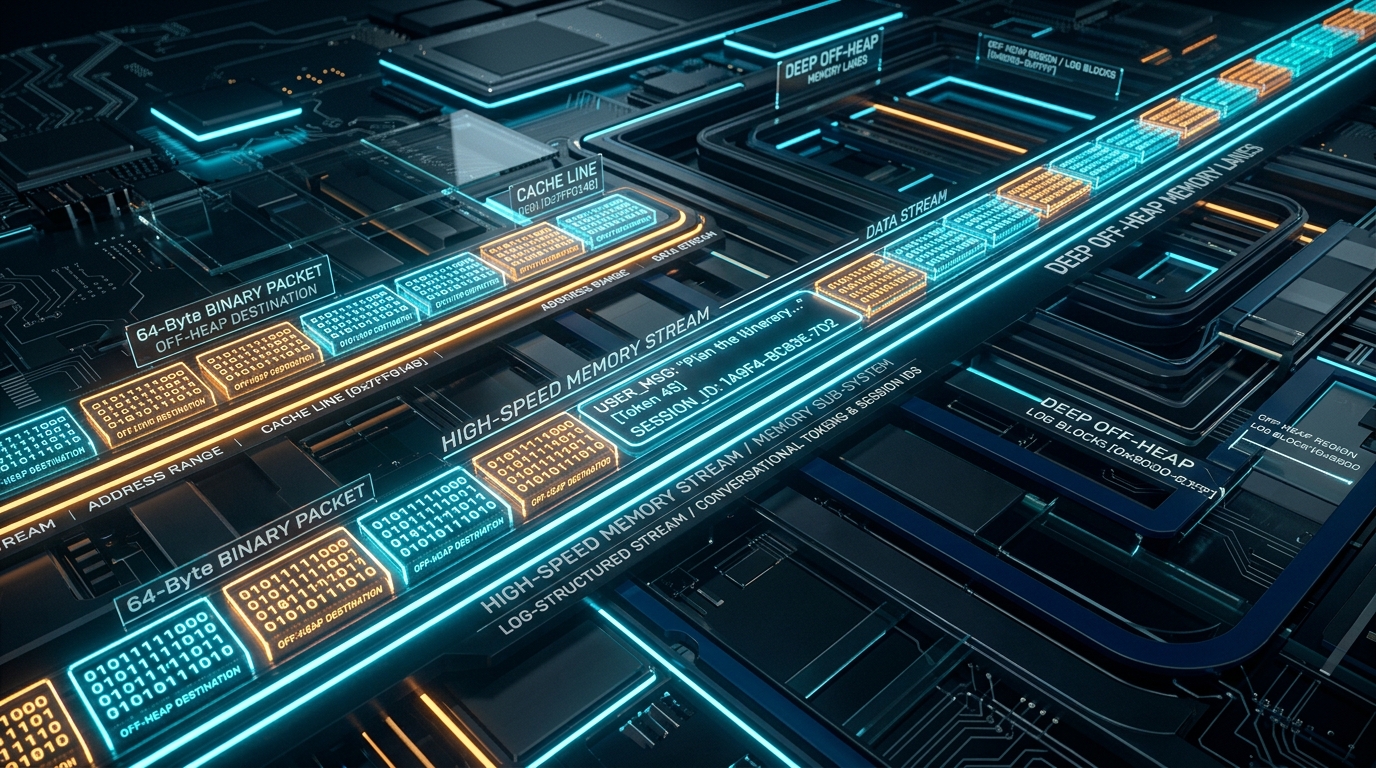
Executive Summary & The Conversational Ingestion Paradox
Every production AI agent framework faces a fundamental trade-off when logging multi-turn dialogues:
- The Heavy Path (Cognitive Ingestion): Generating dense embeddings, calculating BM25 term frequencies, updating HNSW graphs, and traversing Hebbian associations introduces significant per-turn latency. While essential for long-term associative recall, executing this entire cognitive pipeline synchronously on every user and assistant message degrades real-time conversational streaming latency.
- The Fragile Path (Raw Append / JSON Logs): Storing conversation logs in plain text or external document databases avoids embedding overhead but introduces garbage collection churn, OS file lock contention, and high overhead when reassembling recent context windows for LLM inference.
With its Episodic Conversation Architecture, Spector Memory introduces a dual-path engine. By reinterpreting the engine's standardized 64-byte L1 cache-line aligned binary synaptic header for conversation semantics, Spector delivers a dedicated, zero-GC log-structured memory region (EpisodicLogMemory).
Conversational turns are appended with raw CBOR payloads directly into off-heap memory, indexed by 8-byte session hashes in an off-heap index (EpisodicSessionIndex), and instantly retrievable via tailEpisodic(sessionId, N) without scanning or touching vector indices.
flowchart TD
subgraph Ingestion_Paths["Dual-Path Ingestion Pipeline"]
MSG["Incoming Chat Turn (Role, Text, Session ID)"]
MSG -->|Real-Time Chat Turn| EP_LOG["Episodic Log Fast-Path"]
EP_LOG -->|64B Synaptic Header| MMAP_APPEND["EpisodicLogMemory (Off-Heap Mmap)"]
EP_LOG -->|8B TSID Session Map| SES_IDX["EpisodicSessionIndex (O(1) Tail/Browse)"]
MSG -.->|Async Reflection / Consolidation| COG_PIPE["Full Cognitive Pipeline"]
COG_PIPE -.-> EMB["Dense Vector Embeddings"]
COG_PIPE -.-> HNSW["Off-Heap HNSW / BM25"]
COG_PIPE -.-> HEBB["Hebbian / Temporal Graphs"]
end
1. The Binary Reinterpretation: 64-Byte Synaptic Header
In Spector Memory, every off-heap record across all cognitive tiers (WORKING, EPISODIC, SEMANTIC, PROCEDURAL) begins with a standardized 64-byte binary header aligned precisely to an L1 CPU cache line (64 bytes).
Rather than creating a bespoke file format for conversation history, Spector leverages structural polymorphism via EpisodicFieldAccessor. When a record's flags designate conversation logging, the standard cognitive fields are reinterpreted directly in native off-heap memory without data conversion or object allocation:
| Offset | Size | Cognitive Semantic Field | Episodic Conversation Field | Binary Type |
|---|---|---|---|---|
| 0 | 1B | header_version |
header_version |
uint8 |
| 1 | 1B | flags (persistent, encrypted) |
flags (tombstone, consolidated) |
uint8 |
| 2 | 1B | valence (emotional polarity) |
role (USER, ASSISTANT, SYSTEM) |
enum uint8 |
| 3 | 1B | arousal (emotional intensity) |
_reserved |
uint8 |
| 4 | 4B | importance (float32) |
sequence_id (monotonic turn counter) |
int32 |
| 8 | 8B | timestamp_ms |
timestamp_ms (epoch milliseconds) |
int64 |
| 16 | 4B | agent_recall_count |
token_in_count (prompt tokens) |
int32 |
| 20 | 4B | exact_norm (vector L2 norm) |
token_out_count (completion tokens) |
int32 |
| 24 | 8B | synaptic_tags (Bloom filter) |
session_id (8-byte TSID hash) |
int64 |
| 32 | 2B | centroid_id |
model_id (LLM model registry ID) |
int16 |
| 34 | 1B | consolidation_flags |
conversation_flags |
uint8 |
| 36 | 4B | storage_strength |
latency_ms (generation time) |
int32 |
| 46 | 2B | soul_version |
soul_version (agent persona version) |
int16 |
| 48 | 8B | last_auto_ltp |
user_id (8-byte tenant/user TSID) |
int64 |
| 56 | 4B | encoding_surprise |
body_length (inline CBOR payload bytes) |
int32 |
classDiagram
class SynapticHeader64 {
+byte header_version
+byte flags
+byte role_or_valence
+int sequence_id_or_importance
+long timestamp_ms
+int token_in_or_recall_cnt
+int token_out_or_norm
+long session_id_or_bloom
+short model_id_or_centroid
+int latency_or_storage
+long user_id_or_ltp
+int body_length_or_surprise
}
By mapping sequence_id to offset 4 and session_id to offset 24, a single 64-byte read captures the entire conversational telemetry—including token consumption, model provenance, and generation latency.
2. Variable-Length Log Structure (EpisodicLogMemory)
Unlike fixed-stride vector slots, conversation turns vary in length (from short confirmations to multi-paragraph answers).
EpisodicLogMemory extends AbstractAppendMemory, placing the variable-length CBOR document body immediately after the 64-byte header in contiguous off-heap memory:
┌────────────────────────────────────────────────────────────┐
│ 64-Byte Episodic Header (Role, Turn, Session ID, Telemetry) │
├────────────────────────────────────────────────────────────┤
│ Variable CBOR Body Payload (body_length bytes)             │
│ [raw UTF-8 message text, tool invocation payloads, metadata]│
└────────────────────────────────────────────────────────────┘
Zero-Allocation Append Flow
The append operation writes header and payload directly to native memory slices without intermediate Java heap buffers:
flowchart LR
subgraph Turn_Input["Turn Ingestion"]
INPUT["Turn Parameters
(Role, SessionId, Text, Tokens)"] end subgraph Memory_Allocation["Contiguous Offset Reservation"] CALC["Calculate Size
(64B Header + Payload Bytes)"] ALLOC["Atomically Advance Append Cursor"] end subgraph Binary_Stamping["Native Segment Write"] STAMP_HDR["1. Stamp 64B Cache-Line Header
(Offsets: Role, Turn, Session, Tokens)"] COPY_PAYLOAD["2. Direct Memory Copy
(CBOR Payload at Offset + 64B)"] end subgraph Index_Update["Index Publication"] REG["Register Offset in EpisodicSessionIndex
(SessionId -> [Offset List])"] RETURN["Return Physical Byte Offset"] end INPUT --> CALC --> ALLOC ALLOC --> STAMP_HDR --> COPY_PAYLOAD --> REG --> RETURN
(Role, SessionId, Text, Tokens)"] end subgraph Memory_Allocation["Contiguous Offset Reservation"] CALC["Calculate Size
(64B Header + Payload Bytes)"] ALLOC["Atomically Advance Append Cursor"] end subgraph Binary_Stamping["Native Segment Write"] STAMP_HDR["1. Stamp 64B Cache-Line Header
(Offsets: Role, Turn, Session, Tokens)"] COPY_PAYLOAD["2. Direct Memory Copy
(CBOR Payload at Offset + 64B)"] end subgraph Index_Update["Index Publication"] REG["Register Offset in EpisodicSessionIndex
(SessionId -> [Offset List])"] RETURN["Return Physical Byte Offset"] end INPUT --> CALC --> ALLOC ALLOC --> STAMP_HDR --> COPY_PAYLOAD --> REG --> RETURN
3. High-Speed Context Assembly: tailEpisodic
When an LLM agent executes a reasoning step, assembling recent dialogue context must be instantaneous. Traditional memory engines query vector databases or issue SQL ORDER BY timestamp DESC LIMIT N queries, inducing disk seeks and index traversals.
In Spector, EpisodicSessionIndex maintains an in-memory chronological list of 64-bit physical offsets per sessionId. Context assembly resolves physical offsets directly against the memory-mapped segment:
sequenceDiagram
autonumber
participant Agent as AI Agent / LLM
participant Spector as SpectorMemory API
participant Index as EpisodicSessionIndex
participant Mmap as Off-Heap EpisodicLogMemory
Agent->>Spector: tailEpisodic(sessionId, count=5)
Spector->>Index: tailOffsets(sessionId, count=5)
Index-->>Spector: Array of 64-bit Offsets [off0, off1, off2, off3, off4]
loop Zero-Copy Direct Reads
Spector->>Mmap: Read 64B Header + Body Slice at Offset
Mmap-->>Spector: Decoded EpisodicRecord (Role, Text, Tokens, Latency)
end
Spector-->>Agent: Chronological Context List (Ready for Prompt Assembly)
4. Mechanical Design & Architectural Efficiency
The performance advantage of EpisodicLogMemory stems from three hardware-aligned mechanical choices:
graph TD
subgraph Mechanical_Principles["Hardware-Aligned Architecture"]
P1["1. Single CPU Cache-Line Reads (64B Header)"]
P2["2. Zero Kernel Transitions via Off-Heap Mmap"]
P3["3. Pointer-Free Session Hash Indexing (TSID)"]
end
subgraph Operational_Benefits["Operational Advantages"]
P1 --> B1["Eliminates False Sharing & Cache Misses"]
P2 --> B2["Zero Garbage Collection Churn in Chat Hot-Path"]
P3 --> B3["Constant-Time Context Assembly for Streaming Agents"]
end
- L1 Cache Line Alignment: Because the header occupies exactly 64 bytes, reading conversational metadata (role, tokens, latency, session ID) touches only a single CPU cache line, minimizing memory bus traffic.
- Zero-GC Hot Path:
Writing and tailing records operate exclusively through Panama
MemorySegmentslices and primitive value layouts. No intermediate wrapper objects are allocated during dialogue streaming. - Decoupled Real-Time & Cognitive Tiers: User turns are immediately persisted to the episodic log. Heavier cognitive processing (vector embeddings, knowledge graph extraction, circadian consolidation) runs asynchronously in background reflection cycles without blocking the user response.
5. Architectural Takeaways for Enterprise AI
- Decouple Ingestion from Cognitive Consolidation: Do not force real-time user dialogue through heavy vector embedding pipelines synchronously. Log turns immediately into high-throughput binary episodic logs, then promote significant events to cognitive tiers asynchronously during background reflection cycles.
- Standardize Header Geometry: Reinterpreting fixed 64-byte headers across multiple subsystem layers enables unified crash recovery, consistent WAL replay, and predictable off-heap memory accounting across the entire enterprise cluster.
- Session-Indexed Memory Streams: Organizing conversation logs by numeric 64-bit session hashes eliminates expensive document lookups and unlocks true zero-latency multi-session scaling.
Experience Spector Memory
Explore the open-source implementation on GitHub: